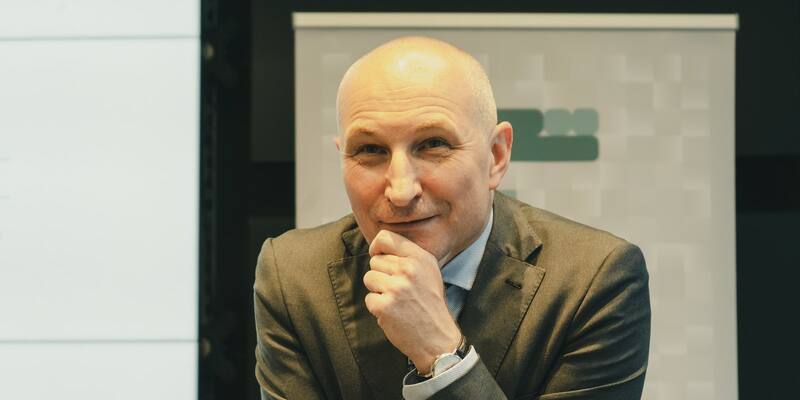
Maciej Szpunar, First Advocate General at the EU Court of Justice, at a Free Knowledge Advocacy Group event in Brussels in June 2022. Image: Paperclip sprl for Wikimedia in Brussels / Wikimedia Commons, CC BY 4.0, cropped

AI chatbots that pull news articles off the web in real time and reuse them in their answers can break the rights of the publishers who wrote them, a senior adviser to the EU’s top court said on Tuesday. Advocate General Maciej Szpunar gave his opinion in Case C-250/25, a Hungarian publisher’s claim against Google’s Gemini chatbot and the first generative AI case to reach the Court of Justice of the European Union.
His answer is a qualified yes: Gemini’s answers can infringe a publisher’s rights “in certain circumstances”. He also told the court to throw out the questions about AI training, because there is no evidence Gemini was trained on the publisher’s articles.
What the Hungarian publisher is claiming
Like Company, which runs several Hungarian news portals, sued Google Ireland in the Budapest Regional Court. It relies on the press publishers’ right in Article 15 of the EU’s 2019 copyright directive (the CDSM Directive), which covers the “online use” of “press publications”. It says Google used its articles to train the models behind Gemini, called Bard until February 2024, and repeatedly reproduced them and made them available to the public through the chatbot between 13 June 2023 and 31 May 2024.
The Budapest court paused the case and sent the Court of Justice four questions. Two ask whether training a large language model on press articles counts as reproduction or falls under the EU’s text and data mining exception. The other two ask whether the chatbot’s answers can breach the publisher’s reproduction right or its right of making works available to the public.
Training: hypothetical, and usually allowed
Szpunar advised the court to declare the two training questions inadmissible. With no evidence that Like Company’s articles were used to train Gemini, and since training a model is not an “online use” of a press publication, he called them hypothetical.
“For the sake of completeness”, though, he suggested that using protected works to train a model is, as a rule, “freely permitted” under the text and data mining exception in Article 4 of the directive. That will disappoint publishers who hoped the court would rein in training, though the exception still lets rights holders opt out in a machine-readable way.
Answers: it depends on the paywall and the wording
The real fight, he said, is over the answers. When a chatbot driven by a language model “retrieves a publication from a press publisher’s website, reuses that publication to generate an answer, and provides that answer to the user”, the publisher’s right may be infringed. Gemini does this through retrieval-augmented generation, or “grounding”, which fetches web pages as a question comes in.
The right protects the “specific form of expression” of an article, not “the mere facts” it reports. Its aim is to protect publishers’ investment, “not to give publishers a monopoly over the news itself”. Whether an answer counts as reproduction turns on two tests, according to the court’s summary:
- Access: did the chatbot reach the article unlawfully, for example by getting round a paywall or other technical measure meant to stop access or scraping?
- Wording: does the answer merely report facts, or reuse the article’s expression so recognisably that the reader no longer needs to open the original?
The making-available right is, as a rule, infringed where the article’s wording is “systematically recognisable” in the chatbot’s answers to related questions. The chatbot provider is liable where such use is “inherent” to its business model, or where it has not put in place measures to counter it “credibly and effectively”.
Not binding yet
An Advocate General’s opinion does not bind the Court of Justice, though judges often follow it. The judges have now started deliberating and will rule later, usually some months after the opinion. The Budapest court will then decide the case itself, applying that ruling. Google and Like Company have not commented on the opinion.
The paywall test lands days after The New York Times sued Brave over AI answers that it says reproduce paywalled Times articles word for word. In the US, a judge threw out suits by Penske Media and Chegg over Google’s AI Overviews, while in Germany two courts have held Google liable for false claims in its AI answers.
Why it matters
If the court follows Szpunar, any AI search tool in the EU that grounds its answers in news, from Gemini and Google’s AI Overviews to ChatGPT search and Perplexity, would need to summarise facts rather than echo articles, and stay on the right side of paywalls. Training on news would stay largely open, so publishers’ leverage would shift to the answers.
Sources: Court of Justice of the EU, press release No 155/26; Case C-250/25, Like Company.
Latest Google news