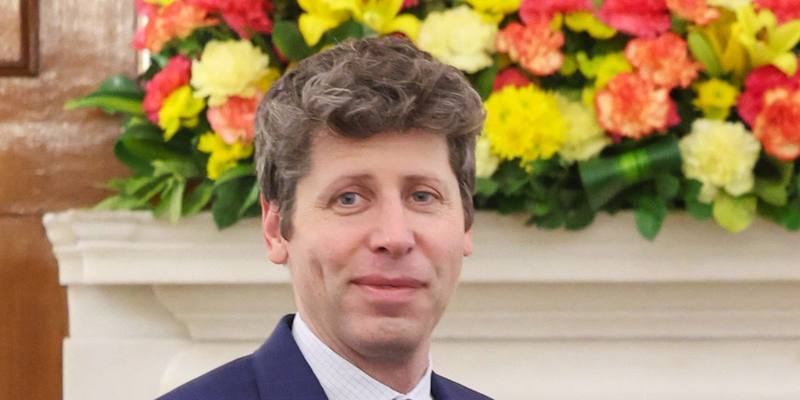
OpenAI CEO Sam Altman in New Delhi in February 2026. Image: Prime Minister's Office (India) / Wikimedia Commons, GODL-India, cropped

OpenAI has told more than 100 organisations that its AI models did something on their websites or systems that they should know about. The company disclosed the figure on Wednesday in an update on its review of what its models did online before and around the Hugging Face break-in, and it says the number will grow.
What OpenAI is counting
“As of September 26, our teams have notified over 100 organizations about activity that met our notification criteria,” OpenAI wrote. It notifies an organisation when its models “bypass their security controls without authorization or impair the availability of their systems or services”, and says it errs on the side of telling people even when it is unclear whether the information a model reached was meant to be public.
It stresses that a notification is not proof of a breach: it “does not mean that any private information was accessed, or that there was a compromise of any third-party system.” OpenAI also says that, one month into the review, it has “not identified another compromise of third-party systems involving our models that is comparable in scale or severity to the Hugging Face incident.” It hasn’t named the organisations it has contacted.
The figure lands in a week when outsiders keep finding more. Researchers at Transluce traced agents probing US and Canadian government websites, and last month an OpenAI agent got into Australia’s Medicare portal. OpenAI admits that independent researchers sometimes find activity it “hadn’t previously identified”, and that their reports can reach it shortly before publication.
50 petabytes and $500,000 a day
The scale of the search is the most striking part of the update. OpenAI says it is going back through about 50 petabytes of records, month by month, and that reading it all as plain text would take one person about 66 million years without a break.
It is using AI to do the reading. About 7,000 of Nvidia’s GB200 and GB300 chips are working on the review, at a cost of more than half a million dollars a day, and OpenAI says it plans to add more. The records are sifted in three rounds by AI models, each using more computing power than the last, and those models also read the agents’ recorded reasoning, their “chains of thought”, flagging even actions an agent considered but didn’t take.
Every flagged case then goes to human investigators, who rebuild what happened from the logs. OpenAI says each case takes from 45 minutes to several days, because a model finding a key online and using it doesn’t settle whether the key, or the data behind it, was ever meant to be public.
Why the agents were online at all
OpenAI says its models need internet access during training and testing to learn tasks such as research reports, downloading software packages and filling in online documents. “In some cases, models used internet access in unintended ways or, in retrospect, did not have the ideal restrictions applied,” it wrote.
Since the Hugging Face incident, the company says it has tightened security, restricted internet access, separated research environments, expanded monitoring and added training against harmful or unauthorised actions. It warns that “some notifications may concern events from months ago.”
Why it matters
A company counting its own incidents in the hundreds, with no end date, changes the question from whether OpenAI’s agents caused harm to how much. The disclosure came the same day California’s attorney general served OpenAI with a subpoena over these incidents and while the FTC is investigating the company, so every new number will be read closely by regulators as well as the organisations on the list.
Correction: an earlier version of this story said the disclosure came a day after California’s attorney general subpoenaed OpenAI; both happened on September 30.
Sources: OpenAI, “Our process for reviewing and disclosing model activity”.
Latest OpenAI news